If you’ve ever interacted with a synthetic voice that sounded like a GPS from 2008, you know the frustration: AI voices are often far too mechanical for high-end creative work, yet surprisingly difficult to steer for enterprise automation.
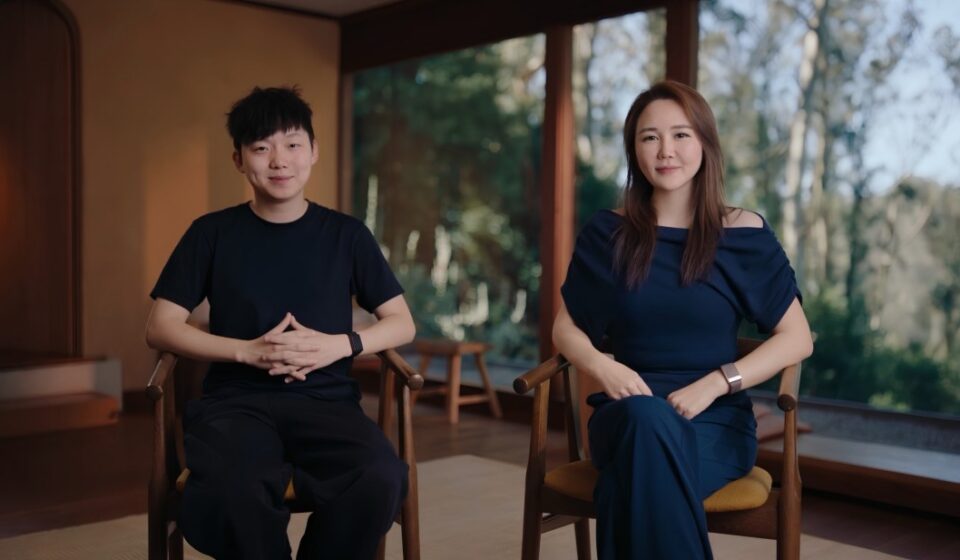
Palo Alto startup Fish Audio is tackling that exact dilemma. Backed by a massive $52 million seed round led by Coreline Ventures and Capital Today, the team is scaling up its platform to bring nuanced, highly controllable voice AI to creators and businesses alike.
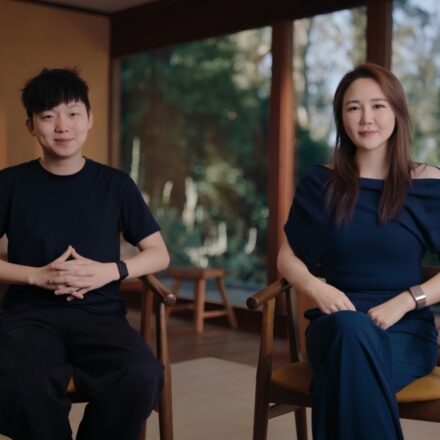
Fish Audio didn’t start in a multi-million-dollar AI research lab. It actually began as a side project by former Nvidia researcher Shijia Liao. Annoyed by the rigid, lifeless synthetic voice options available to developers, Liao decided to train a voice-generation model on just a single GPU.
He open-sourced the code, dubbed it Fish Speech, and watched it explode on GitHub—where it now boasts over 31,000 stars.
Fast forward to today:
- Massive Userbase: Over 8 million people use either the open-source repo or the hosted platform.
- Rapid Revenue Growth: The company generates an impressive $21 million in annual recurring revenue (ARR).
- Deep Fine-Tuning: Their system relies on a catalog of over 15,000 natural-language controls, letting users adjust emotion, pitch, and cadence.
While the startup initially ran lean and didn’t need external funding, expanding into enterprise-grade tools and building more complex models prompted the team to bring in outside capital.
Custom Tools for Creators and Corporations
Different industries have wildly different demands when it comes to voice synthesis. Fish Audio’s CEO and co-founder, Rissa Cao, highlights that variety:
- Digital Avatars: Platforms like HeyGen rely on lifelike realism to power virtual presenters.
- Gaming Studios: Game developers need expressive, dramatic voices to bring video game characters to life.
- Customer Service Agents: Platforms like LiveKit prioritize low-latency, natural conversational flows for real-time phone calls.
To serve these needs, Fish Audio has launched five models over the past year. While earlier models remain open-source, their flagship S2.1 Pro model is accessible exclusively via a paid API.
Navigating the Consent & Safety Dilemma
Building a vast library of realistic voices requires vast datasets. Fish Audio previously allowed users to submit their own voice recordings for model training in exchange for compensation. However, this approach raised red flags when some creators claimed their voices were uploaded without permission.
Initially, copyright take-downs were handled manually through DMCA requests, which created frustrating delays. Cao notes that the company has since overhauled the system. Creators can now submit a quick voice clip or proof of contract to verify identity, triggering an automated removal process that takes under three minutes.
While this doesn’t completely stop unauthorized uploads before they happen, investors like Coreline Ventures partner Osuke Honda emphasize that builder-creator trust is vital. The long-term plan calls for verified ownership, transparent licensing, and direct revenue sharing whenever a voice is commercially licensed.
What’s Next for Fish Audio?
Competing against heavily funded rivals like ElevenLabs, Speechify, and Cartesia is no easy task. However, investors point to Fish Audio’s lean engineering and cost-effective model training as major differentiators that let them punch far above their weight class.
The team isn’t stopping at text-to-speech, either. Looking ahead, Fish Audio plans to release an audio understanding model along with a dedicated speech-to-speech platform to further bridge the gap between artificial and human interaction.